The goal is a model whose predicted probabilities match reality. In conversion modeling the probability is not a ranking score. It is the number you bid on. If the model says an impression is worth 0.2% and the true rate is 0.05, every bid built on that number is wrong by a factor of four. Ranking quality does not save you. The rate is the business.
Building that model is hard because the event is rare, around 0.2%, and because the data is heterogeneous. Banners, fullscreen, CTV and other verticals have different base rates and different failure modes. A model can look fine in aggregate while being systematically wrong on one of them.
The standard answer is calibration evaluation: check whether predicted probabilities match observed rates. A single check is not enough, because errors cancel. Over-prediction in one place hides under-prediction in another, and the aggregate looks clean while the model is broken underneath. That is Simpson’s paradox in production.
This post assumes a labeled dataset of impressions with install outcomes. How that data is collected is outside scope.
Overall totals
Sum all predicted probabilities and compare the total to observed installs. A ratio near one means the model is unbiased in aggregate. For checkpoint selection the variance-normalized squared error, (E−O)^2/E, is useful. Install counts behave roughly like a Poisson, so dividing by the expected value normalizes the squared error by its approximate variance.
The total still suffers from cancellation. That is why the other two views exist.
Probability buckets
Group impressions by predicted probability and compare expected versus actual inside each bucket. Boundaries that double around the training install rate keep resolution where it matters. Equal-width bins on [0, 1] dump almost everything into the lowest one or two bins. Geometric spacing examines both the typical rates and the high-probability tail.
Report the same buckets overall and broken out by vertical. This is the view that exposes the classic pattern of under-predicting low scores and over-predicting high scores (or the reverse).
Feature ECE
For each token value (source app, ad bundle, creative, country, campaign, and so on) within each vertical, compute the absolute gap between predicted and observed installs, then divide the sum of those gaps by total impressions:
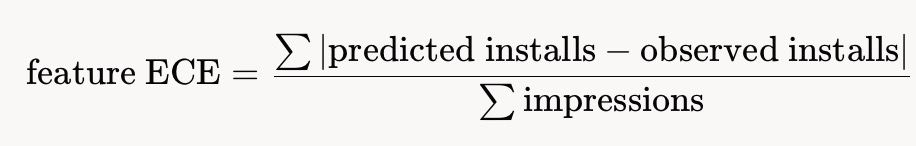
Absolute values prevent cancellation inside a token or across tokens. Keep verticals separate before aggregating, or one traffic type masks problems in another.
This is the most operationally relevant view. A model can look well-calibrated overall while systematically over- or under-predicting particular apps or sellers. Because the model is a transformer with full unmasked attention over a short sequence (typically 10 to 12 tokens), interactions between tokens are already computed by the attention layer. The per-token gaps therefore reflect each token’s contribution in context, not in isolation.
Why not Brier score?
The Brier score is the average squared gap between predicted probability and outcome. At a 0.2 percent conversion rate a model that predicts 0.002 everywhere scores about 0.002, and any model predicting near that looks nearly identical. Differences between a good model and a bad one drown in the fourth decimal place.
Brier does not work as the primary fitness function here. The calibration reports do. Feature ECE and bucket gaps are normalized by impression count, so they do not drown in the base rate. Log loss on the training set and on the validation set, broken out by vertical, catches overfitting and domain-specific failures alongside them.
The agentic loop
The same reports become the eyes of an autonomous agent that trains models with different hyperparameters and different feature sets. The injected context is a distilled summary: the overall ratio, the worst buckets, and the worst tokens per category together with the sign of the error. Not raw output. The pattern, not the scalar.
The agent reads the diagnostics, localizes the failure, proposes a change, retrains, and re-runs the reports. If the worst tokens move closer to observed, the change earned its place. If they do not, the candidate was correlated with the error but not useful, and it is dropped.
A concrete example: the feature report shows a seller token over-predicted by a factor of two. The agent checks whether another available token type correlates with that residual, injects it into the sequence, retrains, and watches the gap shrink from 2× to 1.1×. A second candidate correlates with the residual but does not move the gap after injection, so it is discarded.
Because the sequence is short and fixed in length, the agent optimizes composition rather than length. A token that adds little signal is swapped out for a candidate that adds more. It is not simply appended. The question is not whether to add a feature. It is which token earns its slot.
Two safeguards keep the loop honest. First, repeated runs per configuration. A feature that wins once and loses four times is variance, not signal. Track win rates across experiments, not just the latest result. Second, a fresh evaluation window the agent cannot train on, so any injected token must survive there before it stays.
Limitations
The reports measure calibration. They do not adjust probabilities. Residual bias is handled by a separate post-processing stage. Low feature ECE can still hide problems that only appear in specific combinations of tokens, even though attention computes interactions. And after every change the reports must be re-run to check whether the fix generalized or merely moved the error.
The design (global volume, score-conditional reliability, and feature-conditional absolute error) keeps the common failure modes visible without letting them cancel. In practice the loop changes what the agent does. Instead of guessing which epoch to keep or which token to add, it reads the evidence and acts on it.